
Tag: models
-
Google’s New Flash Model Breaks Its Own Price War
Google just released three new Gemini models on July 21, and the one that matters most is Gemini 3.6 Flash. It’s the workhorse model Google is betting the company will use for 80 percent of the work people actually do. Here’s the thing: it got 17 percent faster while getting cheaper. Fewer output tokens. Lower…
-
Mira Murati Just Released a Trillion-Parameter Open Model
Mira Murati left OpenAI to start Thinking Machines. This week, the company released Inkling, a one-trillion-parameter open-weights multimodal model trained on forty-five trillion tokens, and uploaded it to Hugging Face under an Apache 2.0 license. Open means anyone can download it, fine-tune it, run it on their own hardware. Multimodal means it speaks text, understands…
-

Meta Just Entered the Frontier Model War
Meta released Muse Spark 1.1, a 1-million-token agentic model that rivals OpenAI’s GPT-5.5 and Anthropic’s Opus 4.8 on the benchmarks that matter for real work. The model includes computer use across desktop, browser, and mobile. It can delegate work to other agents in parallel. It has a paid developer API launching in public preview in…
-
Google Just Fired Back With 2M-Token Gemini
Google launched Gemini 3.5 Pro today, and it came loaded. The model carries a 2-million-token context window, Deep Think reasoning that works step-by-step through problems, and stronger autonomous coding than anything Google has shipped before. This is six weeks late. Google scrapped the original base model after finding recursive tool-calling failures and rewrote the whole…
-

The Open Model Bet Got Bigger
Thinking Machines Lab, the research group founded by Mira Murati after she left OpenAI, just released Inkling. It is a 975 billion-parameter open-weights model that you can download, run, and modify yourself. The architecture is sparse. Only 41 billion parameters activate per token, which means it runs fast and cheap despite the enormous size. The…
-
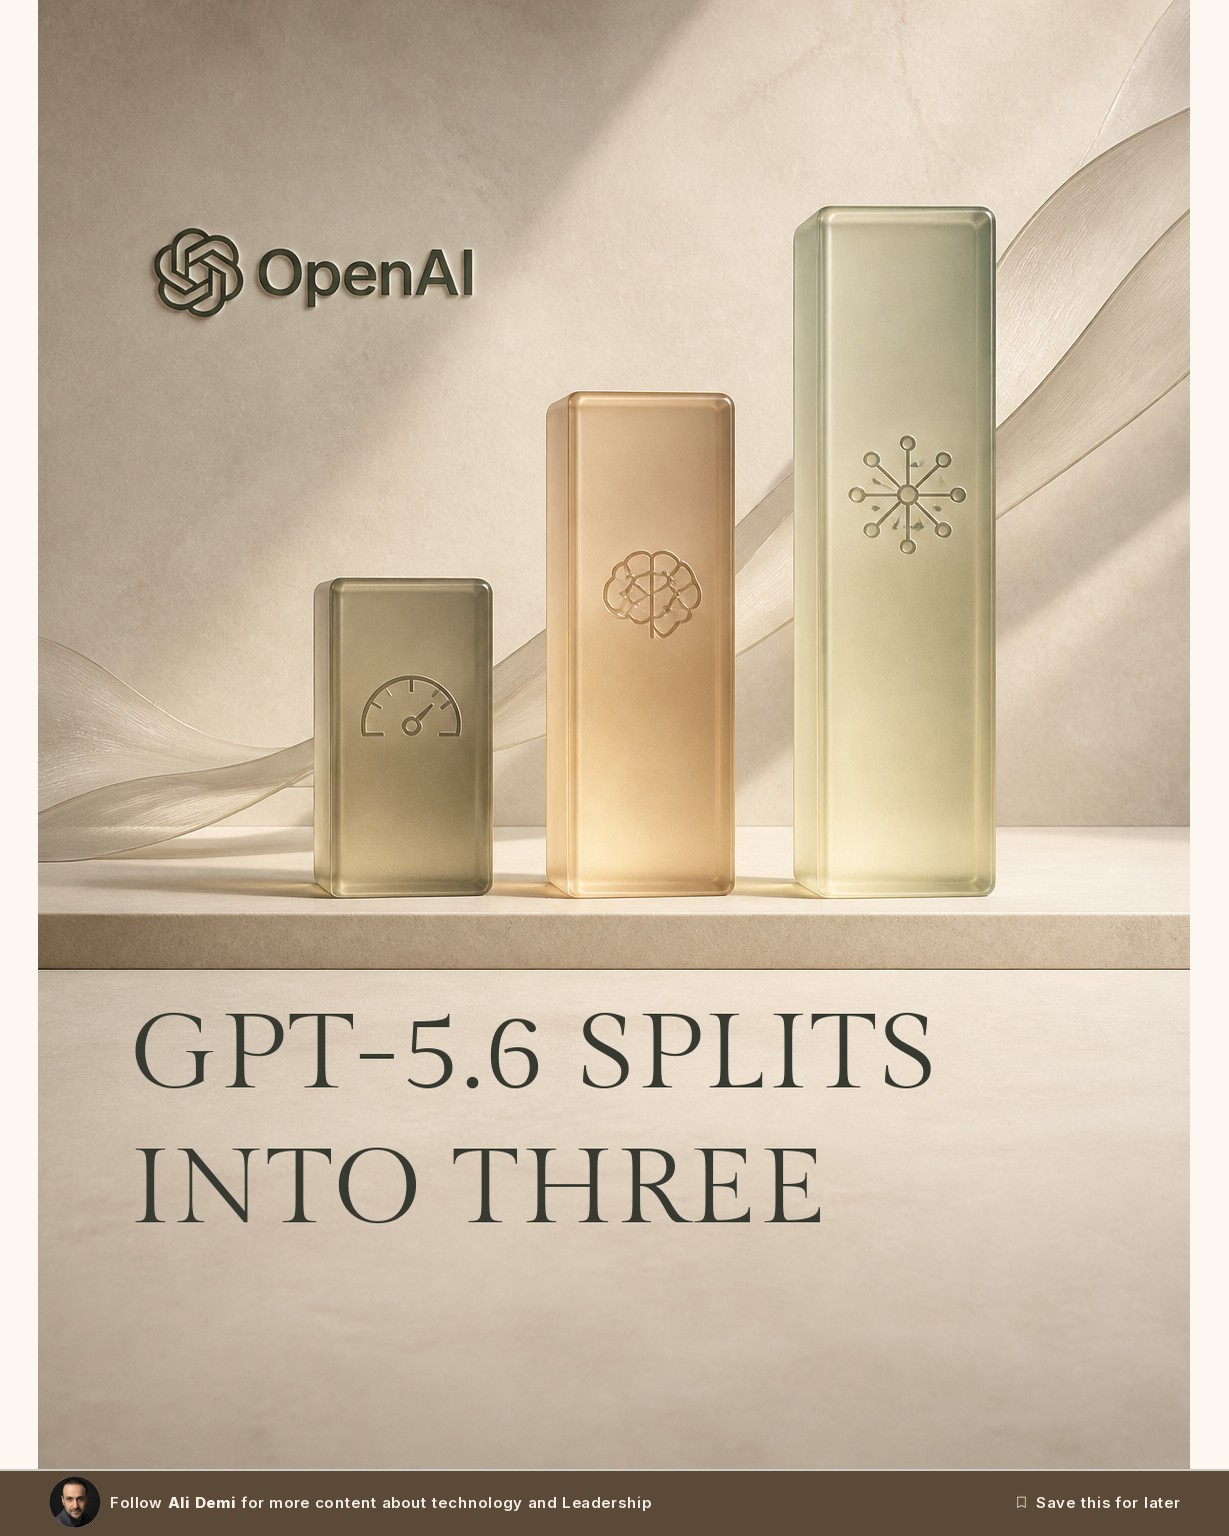
OpenAI Just Split One Model Into Three
OpenAI split GPT-5.6 into three distinct models, each built for a different job. Sol is the powerhouse. Terra is the balanced workhorse. Luna is the fast, cheap option. Sol hits SOTA on reasoning benchmarks. Terra delivers GPT-5.5 performance at half the cost. Luna gets the job done for a dollar per million input tokens. The…
-

Claude Just Hit a New Ceiling on What’s Possible
Claude Fable 5 is now the top-ranked model on the major benchmarks. A hundred out of a hundred on composite quality. That’s not second place. That’s the leaderboard. More important than the ranking is what the ranking measures. It’s not a trick benchmark designed to favor one architecture. It’s the aggregation of real, hard problems:…
-
China Just Open-Sourced a 1.6 Trillion Parameter Model
Meituan, the Chinese food delivery giant, just released LongCat 2.0. It is a 1.6 trillion parameter model trained from scratch on a 50,000-GPU cluster built inside China, and they open-sourced it. Here is what that means: China is no longer waiting for permission to build frontier-scale AI. They are building it anyway, using domestic silicon…
-

Grok 4.5 Is Here, and It’s Trading Blows with Claude Opus
Elon Musk just announced Grok 4.5 is in private beta at SpaceX and Tesla. New foundation model underneath it, 1.5 trillion parameters, fed with Cursor training data. The early reports say it is performing at or above Claude Opus level on hard reasoning tasks. This is not a small update. This is a new architecture,…
-
Asian AI Labs Are Filling Anthropic’s Export Gap
Anthropic’s export mess is already pushing other labs to move. Chinese security firm 360 has unveiled Tulongfeng, and Sakana AI has launched Fugu, both leaning hard on the same opening: if the U.S. gate gets tighter, somebody else will try to serve the market. That is why this story matters. It is not just that…