
Tag: inference
-
Nvidia’s $20 Billion Chip Bet Just Went Live
Nvidia bought Groq’s chip technology back in December for twenty billion dollars, the biggest deal the company has ever closed. That is a huge number to hand over for chips that did not even have a product on the market yet. On Monday, the wait ended. Nvidia said the Groq 3 LPX is now in…
-
A Chip Startup Just Tripled Its Price In A Month
A chip company most people have never heard of just tripled its price tag in about four weeks, and the reason is refreshingly simple. Someone actually plugged the thing in and it worked. Etched makes chips built for one job only, running already trained AI models fast and cheap, instead of trying to do everything…
-

A New Chip Company Just Became Worth 5 Billion Dollars
Etched, a startup that builds specialized chips for running AI models after they are trained, just hit a five-billion-dollar valuation. It also has a billion dollars in signed customer contracts already in the door. This is the company nobody was watching until it showed up. They came out of stealth on July first with eight…
-

NVIDIA Just Slashed AI Inference Costs in Half
NVIDIA announced Rubin, the next generation of their AI chips, and the headlines are about the benchmarks. But the real story is cost. Rubin delivers up to 10 times lower cost per token than Blackwell, their current flagship. That’s not a 20 percent improvement. That’s not a 2x improvement. That’s an order of magnitude shift…
-
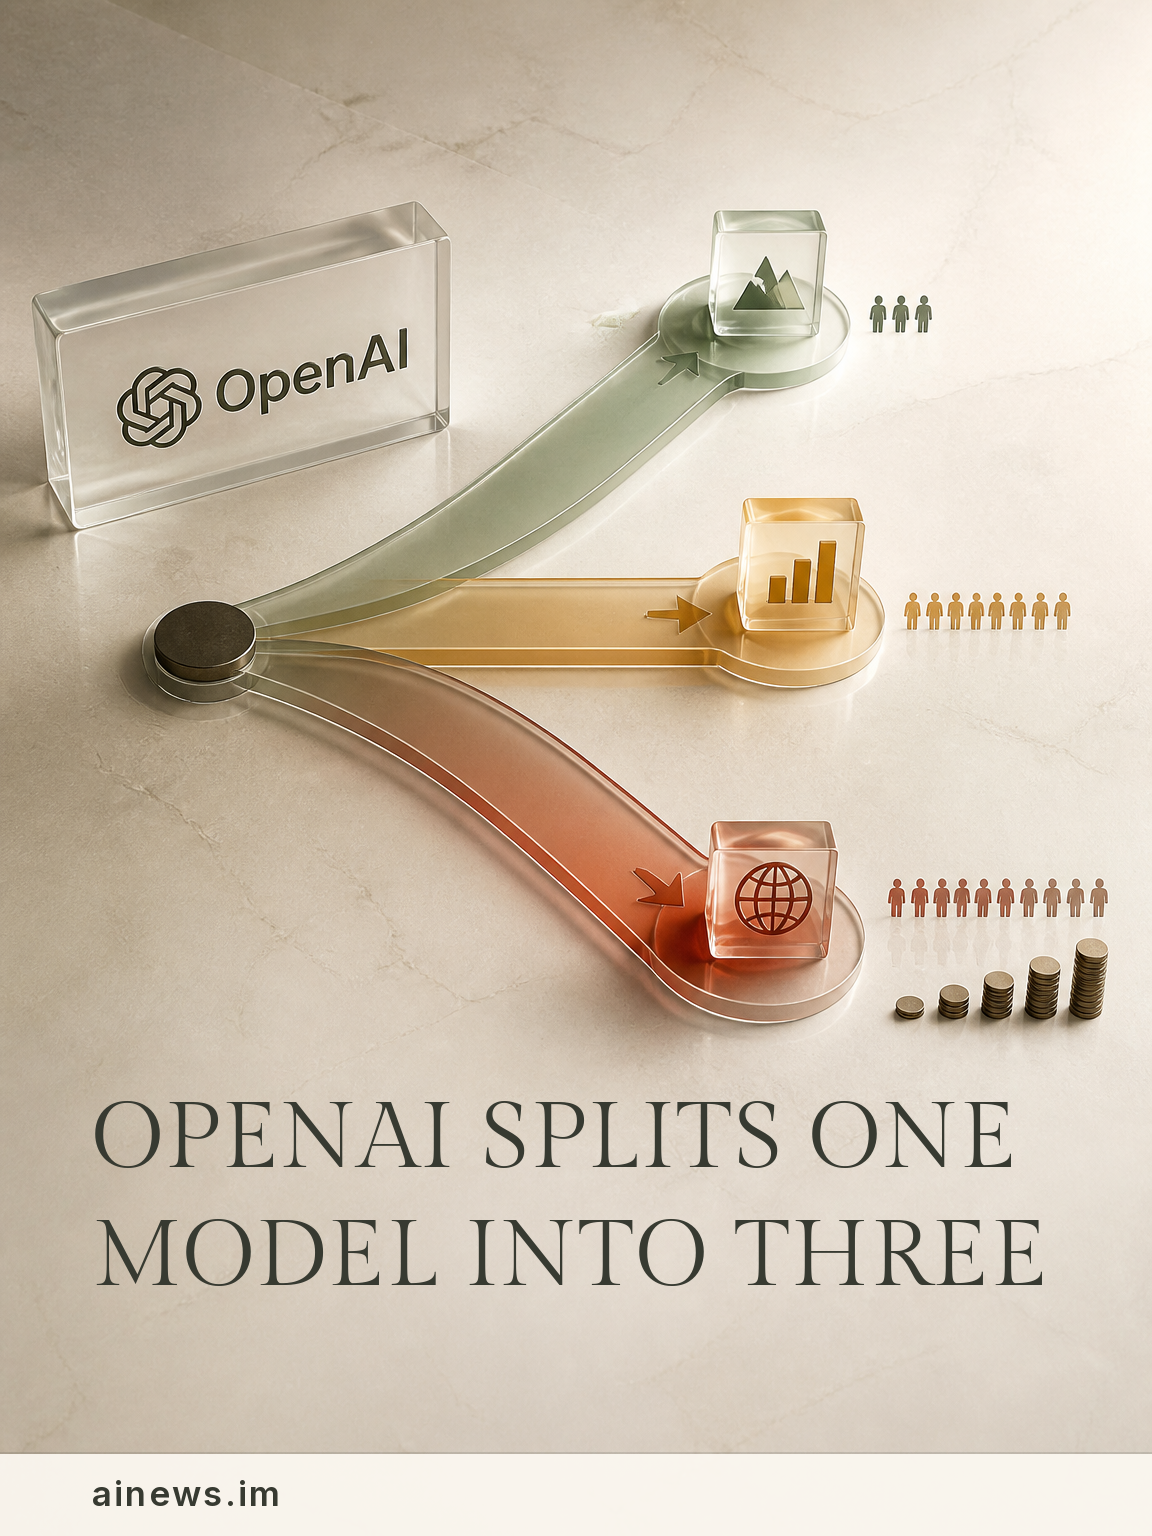
OpenAI’s Three-Tier Model Arrives
OpenAI just released GPT-5.6 in limited preview, and the strategy is clear: stop thinking of one model, start thinking of a portfolio built for real work. Three tiers. Sol handles the hard reasoning tasks, the kind where you throw a 50-page legal contract or a quantum simulation at it and need answers that hold up.…
-

OpenAI’s Jalapeño Chip Just Changed the Game
OpenAI and Broadcom just announced Jalapeño, OpenAI’s first custom AI chip built specifically for inference. This is a moment. Here’s why it matters: the demand for running AI models is exploding faster than anyone can keep up with. OpenAI needed silicon that actually fits what its models do, not generic GPU hardware built for graphics.…